

You change a prompt on a branch... no errors, no complaints. Did you just break something that worked yesterday? The scariest AI failures are the silent ones.
Without a way to know, you get afraid to change your prompts because the chance of breaking what worked without noticing is too high.
The fix: build evals from your own failures. This roadmap shows you how to do it.
1. No Evals Dataset? Here’s How to Build One from Scratch
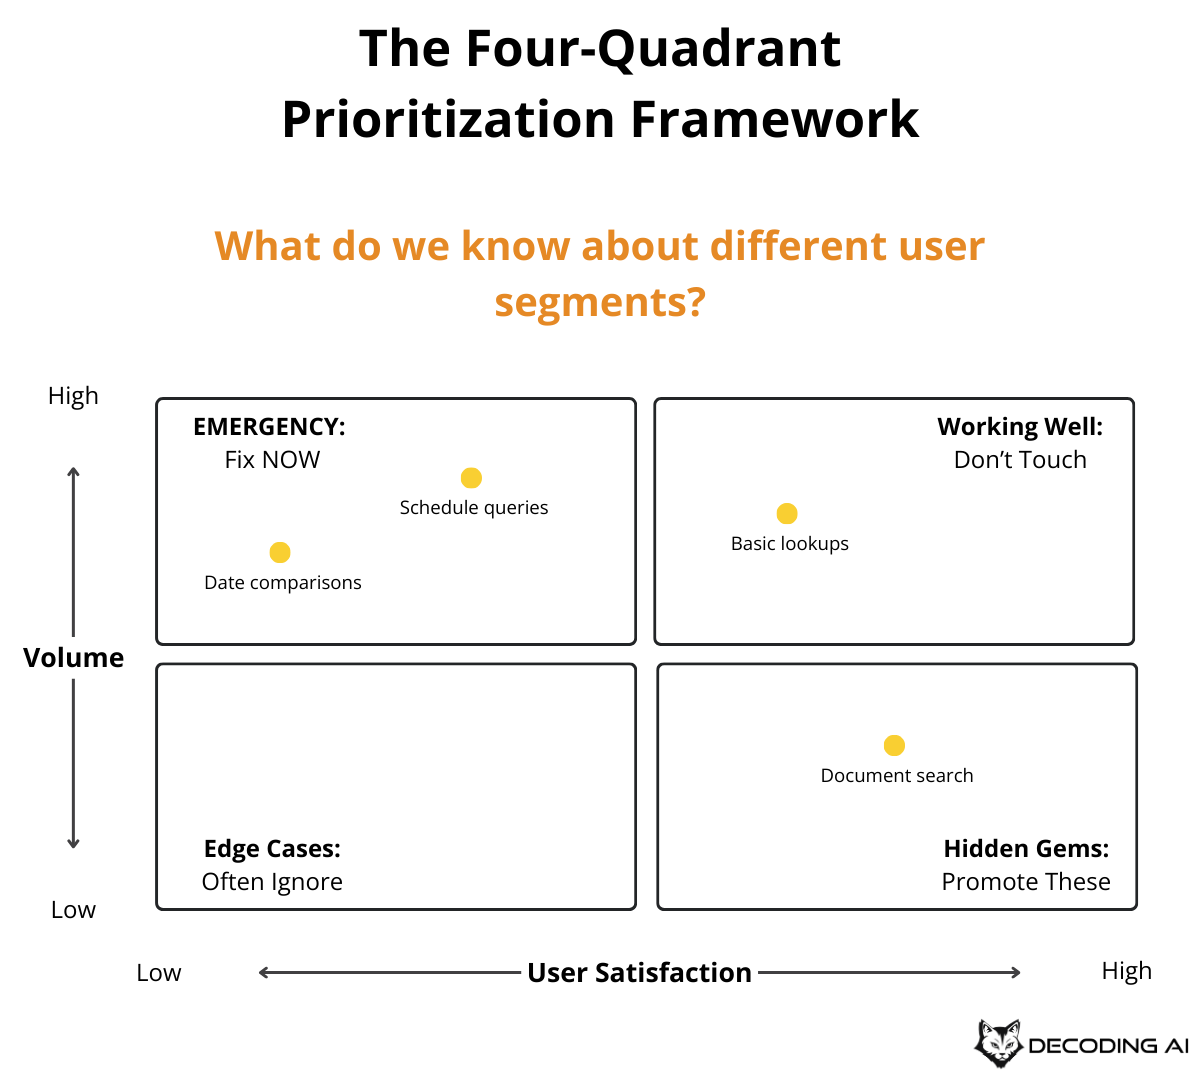
Most teams write elaborate eval criteria before looking at their data. Pull 20-50 real traces instead, and have one domain expert mark each Pass or Fail with a short critique of the first thing that went wrong. Then cluster the failures and rank them by frequency and severity. Your dataset is the secret weapon, not your system prompt.